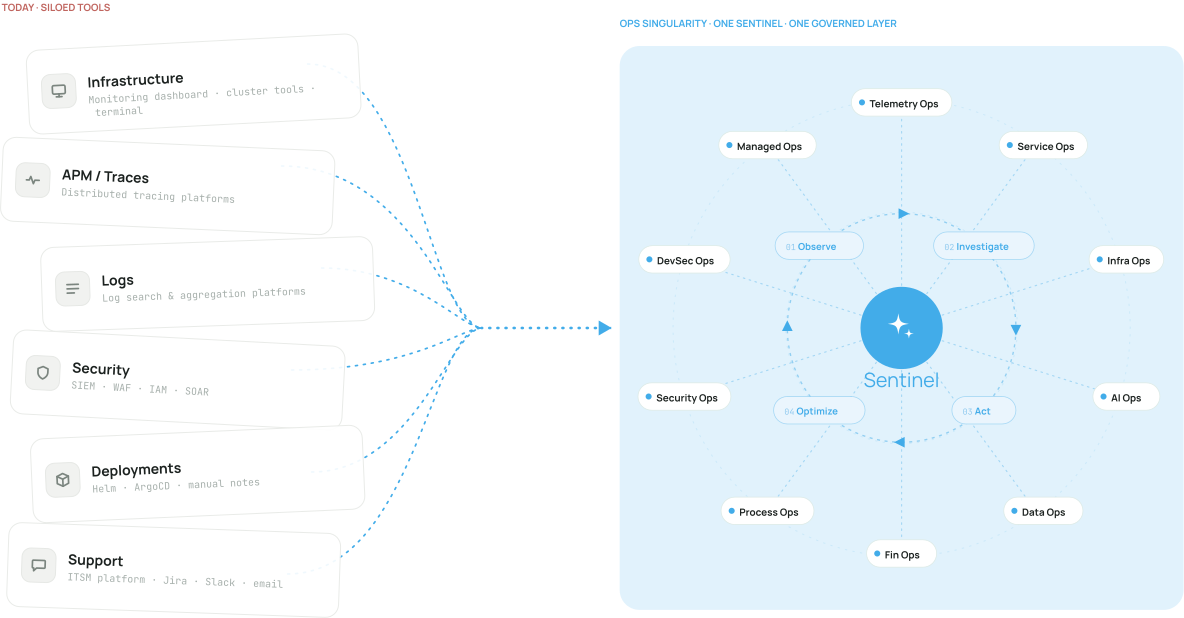
One governed layer over the production stack you already run
Every signal lands in one place and nobody rebuilds context console by console.
Sentinel AI
The intelligence core
Acts with approval, audits every step
Known incident patterns are resolved autonomously under approval policies your team defines.
Error rate spiking on one of your services?
One question, answered across every source in a single pass.
Works with the stack you already run
2,000+ governed integration connectors
Cited RCA and Postmortem
Every finding traces back to its evidence so anyone can verify the reasoning.
| # | Service | Signal sources | Impact | Root cause (cited) | Governed action | Status |
|---|---|---|---|---|---|---|
| 1 | checkout-service | Logs, traces +11 | Service-affecting | Pricing service deploy · 3 citations | Rollback via governed MOP | Awaiting approval |
| 2 | auth-gateway | Identity, SIEM +6 | Security | Brute force on a production server · 5 citations | Call the owner before isolating | Engineer engaged |
| 3 | core-router-edge-17 | SNMP, Kafka +4 | Service-affecting | Optic degradation on uplink · 2 citations | Reroute via MOP | Resolved · verified |
| 4 | payments-api | APM, metrics +9 | Degraded | Connection pool exhaustion · 4 citations | Scale pool, verify SLO | Executing MOP |
| 5 | ilo-node-2231 | HPE iLO, thermal +3 | Predictive | Fan failure, thermal drift · 2 citations | Drain node, open ITSM ticket | Resolved · verified |
| 6 | kafka-broker-03 | Metrics, logs +5 | Degraded | Disk pressure, known pattern · 3 citations | Governed cleanup MOP | Resolved · verified |
| 7 | tick-to-order | Traces, ticks +7 | Service-affecting | Guilty hop: risk engine · 4 citations | Isolate hop in 90 sec | Resolved · verified |
| 8 | bhavcopy-pipeline | Pipeline, data +2 | Low | Late upstream file · 1 citation | Retry with backoff | Resolved · verified |
| 9 | sim-lifecycle | Care console +10 | Degraded | VAS integration timeout · 3 citations | Restart connector | Awaiting approval |
| 10 | billing-vas | ITSM, logs +8 | Low | Config drift after change · 2 citations | Revert config, audit | Executing MOP |
| 11 | k8s-ingress-eu | OTel, K8s +6 | Degraded | Certificate expiry in 48h · 1 citation | Rotate via key vault | Awaiting approval |
| 12 | user-login | Identity, logs +3 | Low | A user fails login five times · 2 citations | Report before the user complains | Resolved · verified |
In production at
carrier-scale enterprises
650
services under monitoring
~62,000
telemetry rows ingested per second
27,000+
devices under one governed NOC
Observe · Investigate · Resolve · Optimize
Observe, investigate, resolve and optimize under one governed layer.
01 End Tool Sprawl
Your ops team is drowning in tools, not answers.
One layer, not another tool: Integrates with and leverages what you run today. We do not change your tools; we make them work with each other.
Cross-platform federated detection: Correlates across ITSM, ERP, CRM, HR and identity, incidents no single-platform AI can even see.
Open by design: OpenTelemetry-native ingestion for logs, metrics and traces; every other source arrives through governed connectors. Your telemetry stays portable.
2,000+
governed integration connectors
02 Resolution, Not Detection
Detection is table stakes. Resolution is the job.
Service-affecting first, with evidence: Incidents that touch the service are identified and prioritised first, and every finding traces back to its evidence so anyone can verify the reasoning.
Conversational operations: Engineers investigate in plain English; L1 triages with evidence that used to need an L2, and mundane diagnostic legwork disappears.
Proactive, human in the loop: A user fails login five times? Sentinel has pulled the logs and reported before the user complains. Brute force on a production server? It calls the owner before isolating.

43%
average MTTR reduction, measured in production
03 Production Hardened
Production hardened, from day one.
Built by people who run production: The same team operates carrier-scale NOC and managed services estates today. The platform ships with that operational muscle memory built in.
Security first, certified to prove it: Zero-trust foundation with role-based access control, key vault and runtime protection as the baseline, certified to ISO 27001 and SOC 2 with GDPR-assessed data handling. It integrates with the vault, WAF and identity you already trust.
Scalable by design: A petabyte-scale data foundation, with investigations and procedures running as containerized jobs in parallel across your estate. Measured in one live deployment: 650 services under monitoring, with around 62,000 telemetry rows ingested per second across metrics, logs, traces and profiling.

6-9
months live in production across enterprise deployments at carrier-scale estates.
04 Governed AI
AI you can trust with production data.
Curated & anonymised before any model: Raw production data is never handed to a model; the Data Governance Fabric filters and masks first.
Typed least-privilege: Sentinel reads; ProcBot and Sherlock act, each under explicit, scoped grants. No component holds more access than its job.
Explained, with citations: Every finding traces back to the evidence it was drawn from. An engineer who asks why a fix was applied gets the answer with the evidence behind it, not a black box.

Every
decision explained, with citations
05 Knowledge Retention
Tribal knowledge that stops walking out the door.
Documented once, runs governed: Operations procedures, and the business processes that depend on them, become governed MOPs that L1, L2, L3 engineers or the platform itself can run.
Validated, not assumed: Sherlock checks every fix against live metrics and scores procedure effectiveness.
New engineers inherit years of knowledge from day one: They execute proven procedures from day one instead of learning by outage.

~60%
of routine, mundane operations automated
06 On-Prem · Air-Gapped · Sovereign
On-prem. Air-gapped. Sovereign to the model.
The AI stays home too: LLM inference on your hardware: bundled open-weight reasoning models (120B-class), or local models you bring, benchmark-tested against operations workloads before rollout. No callbacks, no third-party model APIs, no training on your data.
Air-gapped is the same platform: Full capability inside your perimeter, updated by signed offline artifacts. Not a reduced variant.
Sovereign for the strictest reviewers: Data residency by construction for regulated enterprise and government, with audit trails and lineage generated as operations run.

0
data egress required
07 Own Your Automation
Own your automation. Not another vendor's roadmap.
Your logic, your IP: What your team builds in the Studio stays yours: versioned, exportable, and reusable across your estate.
Open standards, no DSL prison: OpenTelemetry-native signals and standard tooling like Ansible, Python and shell, so nothing you write is trapped in a proprietary language.
Extend without a services army: Low-code building means your engineers tailor the platform themselves; the vendor dependency ends where your team begins.

100%
of what you create is your IP
08 Service as Software
Software that finishes the work.
Outcomes over access: You are not buying screens for your team to operate. The loop delivers resolved incidents, executed procedures and verified outcomes, visible on your numbers.
From operators to orchestrators: Your team designs the feedback loops and sets the guardrails and circuit breakers: approval gates, blast-radius scoping, hard limits. Autonomy expands as trust accrues.
Not just done. Done well.: Every decision is interpretable, with evidence and citations, and Sherlock scores each fix against live state, so effectiveness is measured, not assumed.

~60%
of recurring faults resolved end to end
Recorded deployments, basis stated
Security first, certified to prove it
It integrates with the vault, WAF and identity you already trust.
ISO 27001
SOC 2
GDPR assessed
Zero-trust foundation with role-based access control
Key vault and runtime protection
On-prem, your cloud, or air-gapped
Raw production data is never handed to a model; the Data Governance Fabric filters and masks first.
Read the security & governance architecture →
Asked before every evaluation. Answered here.
Nine questions that come up in nearly every first conversation, answered plainly. The full set, including pricing, POC mechanics and integration depth, lives on the FAQ page.
Browse all questions →Opstral is an AI-native platform for enterprise operations. At its center is Sentinel AI, an autonomous intelligence engine that observes your signals, investigates anomalies, determines root cause and takes corrective action under governance. It is built for NOC, SRE, platform engineering and IT operations teams running complex estates at scale.
No. Observability tells you what happened; it is an input to Opstral, not what Opstral is. The platform investigates why it happened, determines the appropriate response, coordinates enterprise knowledge and automation, and executes under governance across heterogeneous, multi-vendor environments.
No. Opstral sits on top of your existing stack, integrating with and leveraging tools like Dynatrace, Datadog, New Relic, Splunk, Prometheus, Grafana and PagerDuty. Sentinel consumes signals from your existing sources, correlates them and acts; those tools continue to do what they do well, and Opstral makes them work with each other.
Service as Software is the inversion of SaaS: instead of a tool your team operates, the platform delivers completed work: resolved incidents, executed procedures and verified outcomes. Governed means every action is scoped to a blast radius, approval-gated where policy requires, reversible and fully audited.
Yes. Opstral is built for on-prem, air-gapped and sovereign deployment, including the AI itself: LLM inference runs inside your perimeter on your hardware, with self-hosted models Opstral ships or local models you bring. No telemetry leaves your environment, and updates arrive as signed offline artifacts.
Much of it they already have, and Opstral keeps it: Ansible, Python and shell scripts become governed, versioned MOPs on day one. But scripts automate known responses; they do not investigate, and nobody scripts judgment across heterogeneous signals. You are buying the investigation layer, the governance and the institutional memory.
Your operations keep running. Opstral is a layer over your tools, not a replacement: your monitoring still monitors, your ITSM still tickets, and your team can operate everything directly at any time. And if you leave, you take your work with you: every MOP, agent and dashboard your team built is your IP, exportable and runnable outside the platform.
Not because your engineers lack skill; because no human can query every console at once. Opstral holds a live, governed connection to every signal source, so it investigates all of them in parallel, applies every documented procedure instantly, and never loses context between incidents. Your team gets the same powers through plain-English investigation.
Trust in production is a governance question more than an AI question. Recommendations carry evidence, confidence and reasoning; production-changing actions run through approval policies and your change management; and executed actions are reversible and audited. Autonomy is graduated: the platform earns trust with evidence, not promises.